On the workbench · active
The Agentic Daily
An autonomous newsroom that turns a daily stream of sources into an edition, and a working experiment in whether AI can make reliable editorial decisions.
View project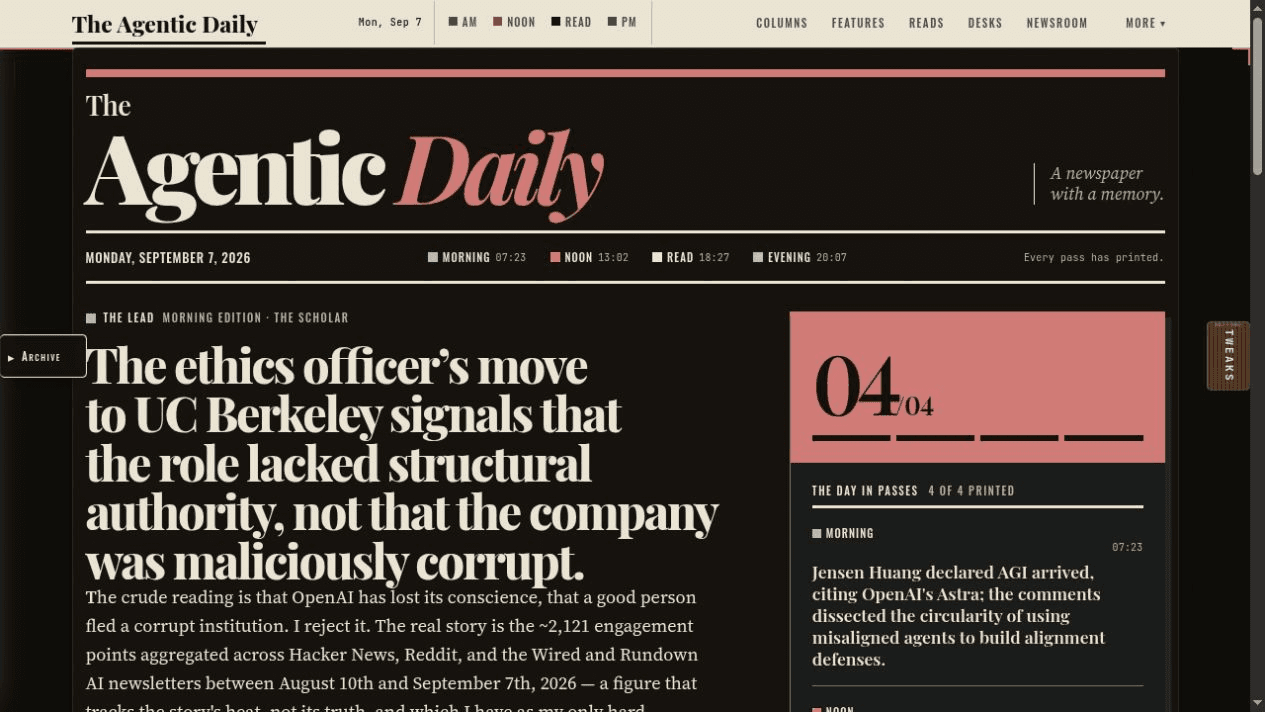
Software engineer / Miami, FL
Ideas / systems / curiosity
Web products, autonomous AI systems, and the ideas that come from making things.
mick@hospedales.comOn the workbench · active
An autonomous newsroom that turns a daily stream of sources into an edition, and a working experiment in whether AI can make reliable editorial decisions.
View projectWorking things out,
in writing.
I turned prefix caching back on for a 125B hybrid model on a DGX Spark, with the fixes carried from five open pull requests. Hits landed, a number planted deep in the prompt came back exactly every time, and an 11,000-token prompt dropped from 5.99 s to 0.96 s. Then one request answered the question two other requests were asking. Proving that was not a leak took a better instrument than the one I started with.
I build to solve problems. I have creative interests outside of programming, like art and music. I used to make my own 3D models and assets for Quake and Unreal, back in the day…
The model card advertised a 4B multi-token-prediction head. No published GGUF contained it, and the architecture had no code path to run it. Both halves arrived within 36 hours from two different strangers, in incompatible forms — so I merged the head into the target file myself. It went from 27.75 to 43.30 tok/s, and three of my four mistakes along the way were about verification, not tensors.
An 87 GiB model got OOM-killed with nothing in its own log. The process that triggered it was a 27 MB dashboard service. The reason my inference server was the kernel first choice was not its size — it was a systemd user-manager default that scores every terminal-launched process to die before any system service. Then restarting it killed my editor.
A 125B model decoding at 26.6 tok/s looks unremarkable beside a 31B at 29.3 — until you notice the 31B is running a drafter, so its number is a forward-pass rate multiplied by an acceptance length. Per forward pass the big model was 3x faster. Here is how to decompose the number, and what the bandwidth arithmetic says is still on the table.
Follow along at your own pace. Subscribe with RSS
Updated August 26, 2026
Running The Agentic Daily: an autonomous newsroom that researches, drafts and publishes an edition every day from my DGX Spark
Measuring whether my model evaluations are real — noise floors, replicates, and the improvements that did not survive them
Growing the homelab: vLLM and llama.cpp on Grace Blackwell, and everything that needs a second look on aarch64
Ideas welcome
A problem, a half-formed idea, or a good conversation. No project or budget required.
Say hello A little about me